
Authors: Adel Daoud | Connor Jerzak | Richard Johansson
TL;DR
- Treatment leakage is when your text contains information about treatment assignment, not just confounders.
- Conditioning on leaked text can create post-treatment (collider) bias and can even break overlap by making treatment almost perfectly predictable from text.
- Text distillation is a preprocessing step that removes treatment-related signal from the text so you can still adjust for confounding without adjusting for post-treatment information.
- In the paper’s simulation, using non-distilled text made ATE estimates worse, while distilled text substantially reduced bias.
What is “treatment leakage” in text-based causal inference?
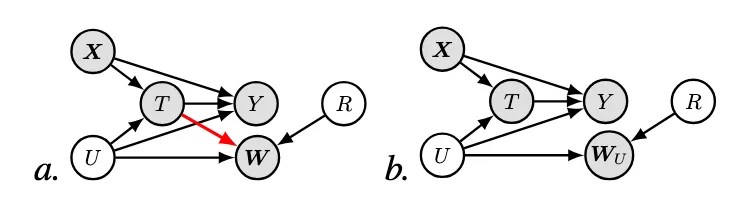
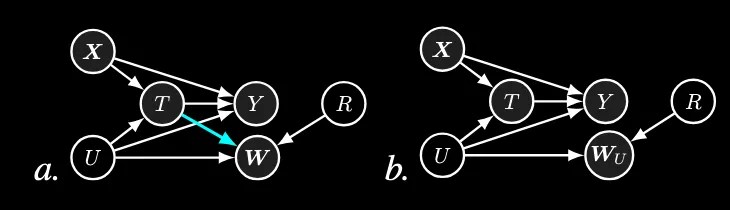
Treatment leakage happens when your text variable W is affected by treatment status T, even after accounting for an (often unobserved) confounder U. In other words, the text carries treatment information, not just confounder information.
One formal way to express this is:
\textbf{Treatment leakage:}\;\; W \not\perp T \mid UIn the simplest version, you can imagine the document has (at least) two parts: a treatment-related portion WT and a confounder-related portion WU. But in many real applications, leakage isn’t neatly “sectioned off”—treatment can shift tone, sentiment, or style across the whole document.
Why does treatment leakage create post-treatment (collider) bias?
If treatment affects the text, then conditioning on the text can “open” biasing paths in your causal graph—equivalent to conditioning on a post-treatment variable (a collider), which generally biases the estimated effect.
Conceptually, you wanted text to act like a proxy for unobserved confounding. But once text is contaminated by treatment, you’re stuck with an uncomfortable tradeoff: either
- adjust for text and risk post-treatment bias, or
- don’t adjust and risk unobserved confounding bias.
How do you detect treatment leakage in your text features?
If your model can predict treatment status from text unusually well, you should suspect leakage—especially if the text is written after treatment or explicitly references the intervention. This often shows up as overlap problems (propensity scores piling up near 0 and 1).
Quick diagnostic checklist
- Timestamp check: Was the document produced after treatment assignment? If yes, leakage risk is high.
- Keyword scan: Does the document literally mention the treatment (e.g., program names, policy rollouts, prescribed meds)?
- Predictability test: Fit a simple classifier Text → T. If AUC is extremely high, you may be modeling post-treatment signal rather than confounding.
- Propensity distribution: If estimated propensities cluster near 0 and 1, you may be violating overlap.
Tip: Leakage is especially sneaky because text can reference past and future in the same document, revealing treatment information even when you didn’t intend it to.
What is “text distillation,” and how is it different from normal preprocessing?
Text distillation is a preprocessing step designed specifically to remove treatment-related content (tone, words, sentences, paragraphs) from the text so the treatment signal is “negated” before you use text for adjustment.
That’s different from typical NLP preprocessing (tokenization, stopword removal, stemming), which targets noise or sparsity—not causal validity. Distillation exists to make conditioning on text closer to conditioning on WU (the confounder-bearing part of text) rather than the full W.
What distillation is trying to achieve (in one line):
\text{Find } f(\cdot) \text{ such that } W^* = f(W) \text{ removes treatment signal while keeping confounder signal.}When does text distillation work (and what assumptions do you need)?
Distillation is most straightforward when treatment-related passages and confounder-related passages are separable (they don’t overlap). When separability fails (e.g., treatment changes the entire tone), you need a stronger requirement: the transformed text must be conditionally independent of treatment given the confounder.
Assumption 1: Separability (best-case scenario)
If text can be decomposed into non-overlapping parts, the separability assumption can be written as:
\textbf{Separability:}\;\; W_U \cap W_T = \varnothingAssumption 2: Stronger “independence after transformation” (harder case)
When leakage is diffuse (tone/style), separability may not hold. Then distillation relies on making the transformed text W* independent of T given U, while still maintaining information about U.
Why text is unique: Unlike many numeric proxies, text is readable—researchers can often manually audit whether the distilled text still “sounds like” it contains treatment details.
What did the paper’s simulation show about leakage and distillation?
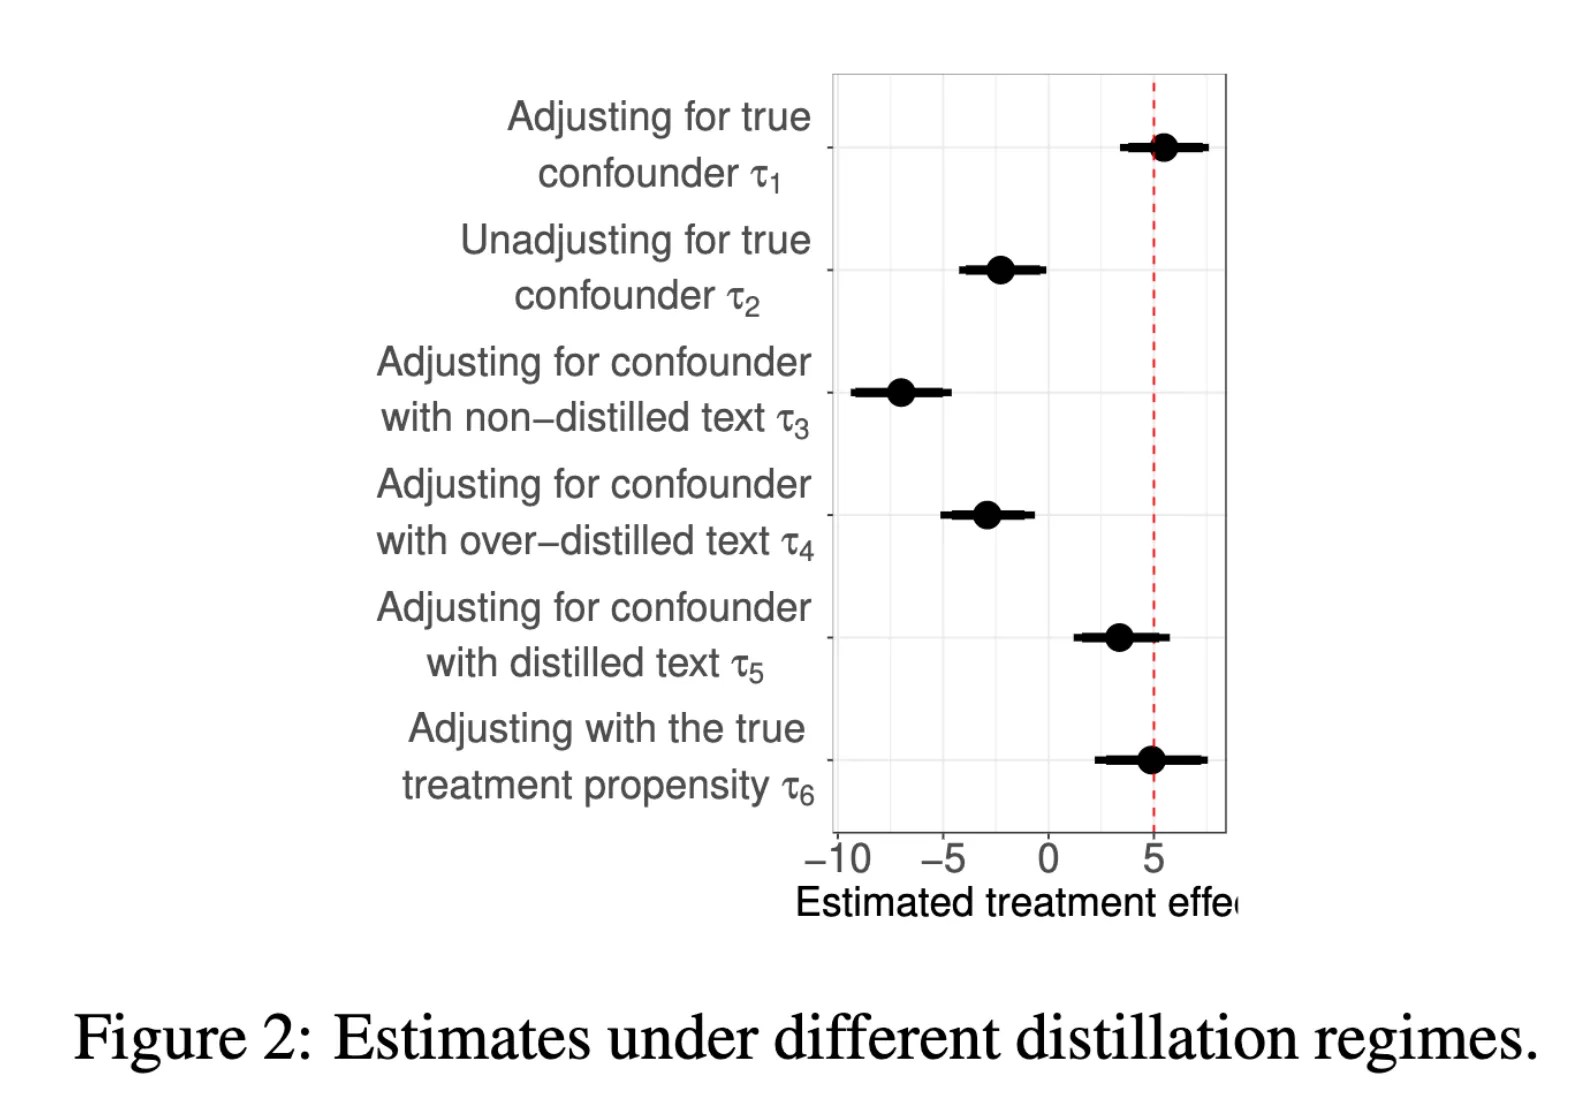
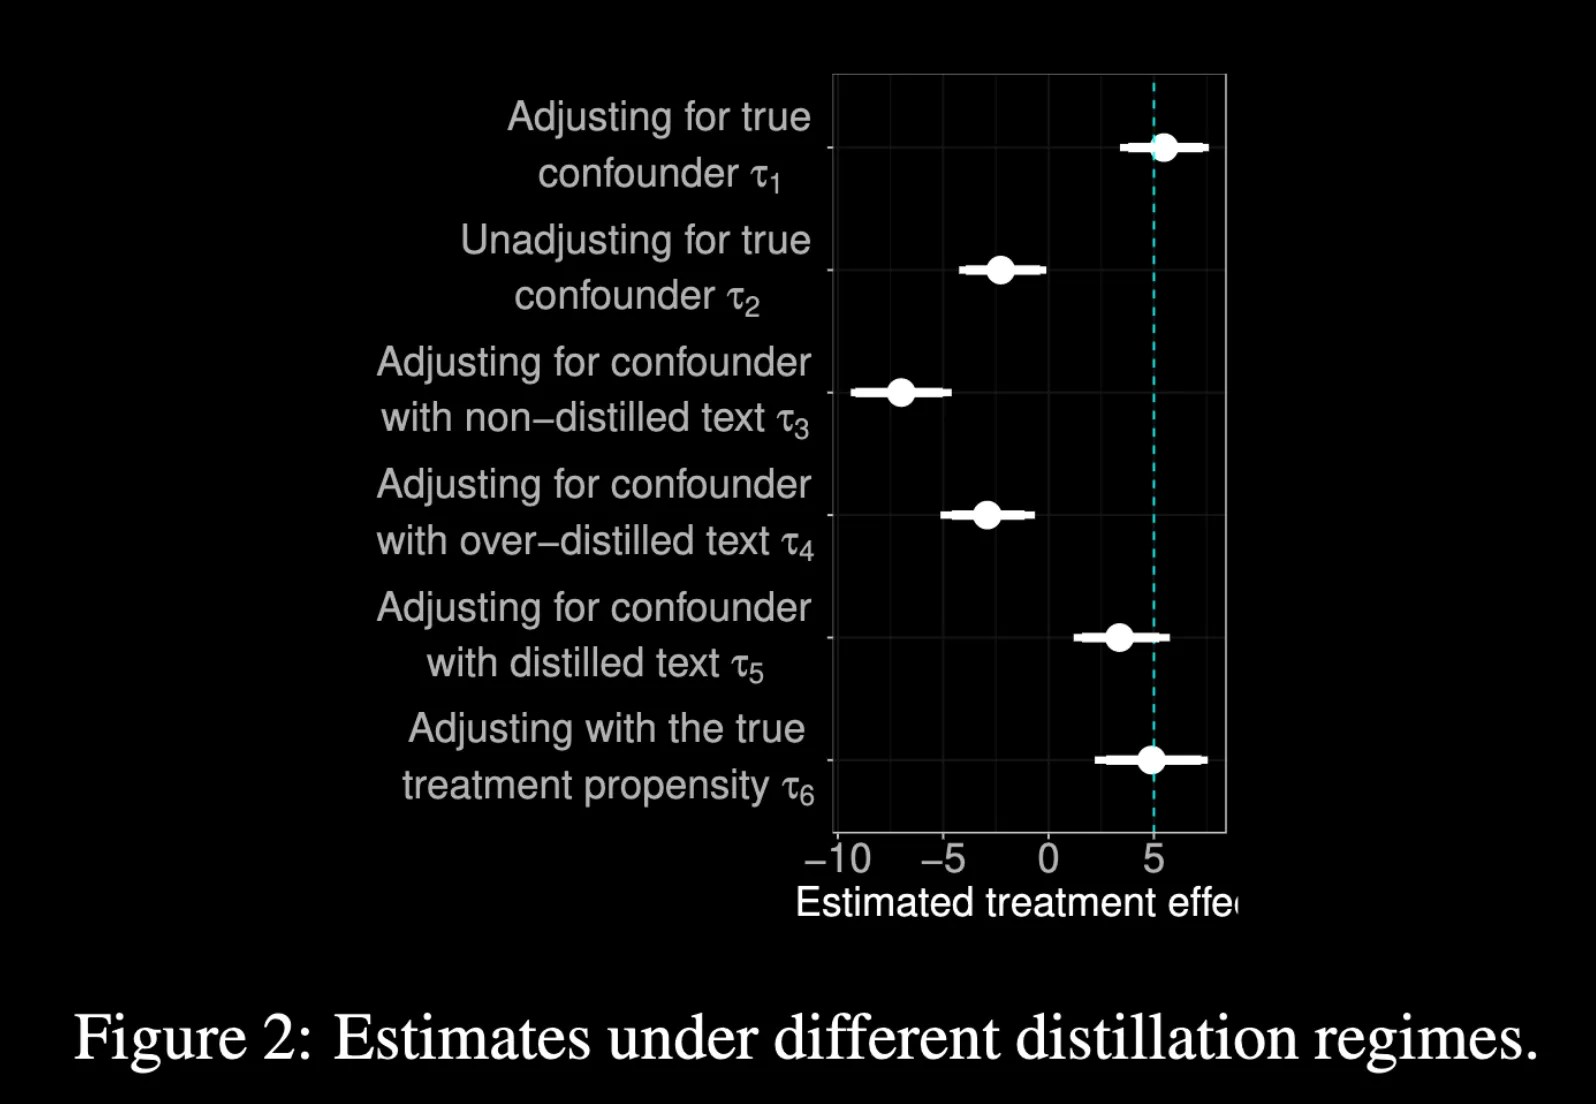
In simulation, using non-distilled text to estimate propensities made ATE estimates more biased than adjusting on non-text covariates alone; oracle distillation substantially reduced bias; and using true (simulated) propensity scores produced estimates close to the ground truth.
Key numbers (from the results section)
- Without distillation, the IPW estimate using text produced \hat{\tau}_3 = -7.0 (with a confidence interval far from the true effect).
- With oracle distillation (removing treatment-affected paragraphs), the estimate improved to \hat{\tau}_5 = 3.5 and its CI covered the true effect.
- With the true (simulated) propensity, the IPW estimate was \hat{\tau}_6 = 4.9, nearly on top of the data-generating effect.
The mechanism is intuitive: without distillation, estimated propensities cluster near 0 and 1 (treatment is almost perfectly predictable from text), while distillation makes estimated propensities resemble the data-generating propensities and restores overlap.
How do you apply text distillation in real-world causal inference (a playbook)?
Treat distillation like you would treat covariate construction: define what “treatment signal” looks like, remove it (or project it out), and verify that the remaining text still proxies confounding rather than treatment. You can think of this as removing WT to keep WU for adjustment.
-
Define treatment leakage for your domain.
Write a “leakage spec” listing explicit treatment mentions, downstream consequences, and post-treatment narratives. -
Choose a distillation unit.
Paragraph-level is often practical (and matches how many real documents are structured). -
Build a distillation method f.
Options include (a) human annotation rules, (b) supervised classifiers for “treatment-related text,” or (c) representation learning approaches that remove treatment information while preserving other signal. -
Audit the output: can you still predict treatment?
Re-run a Text → T model. If it’s still extremely predictive, distillation likely failed. -
Audit confounder proxy strength.
If distillation is too aggressive, you may also remove confounder signal (proxy-faithfulness issues). -
Estimate effects with your causal estimator of choice.
The paper demonstrates IPW (propensity modeling + weighting), but the leakage issue—and the need to avoid post-treatment adjustment—generalizes beyond IPW.
Guardrail: When the no-treatment-leakage assumption is violated and text is heavily contaminated by treatment, effect estimates can be severely biased, and you may be better off not using non-distilled text for adjustment.
Treatment leakage vs. “data leakage” vs. label leakage: what’s the difference?
Treatment leakage is a causal problem: text contains post-treatment information about T that you condition on, biasing your causal estimand. “Data leakage” (in ML) usually means your training pipeline accidentally uses information that wouldn’t be available at inference time.
- Treatment leakage (causal): Conditioning on leaked text can introduce post-treatment (collider) bias.
- Label leakage (predictive): Text features contain direct hints of the label, inflating accuracy.
- Data leakage (pipeline): Train/test contamination, target leakage, or time-travel features.
If you do causal inference with text, you can have both: a pipeline leakage issue and a causal leakage issue. Distillation is aimed at the latter.
FAQ: Treatment leakage and text distillation
What is the average treatment effect (ATE) in this context?
The ATE is the expected difference between potential outcomes under treatment and control: \tau = \mathbb{E}[Y(1)-Y(0)].
Is treatment leakage only a problem when text is written after treatment?
Post-treatment text is the most obvious risk, but leakage can also arise when text references future or past states in ways that reveal treatment assignment.
Can text distillation be “too aggressive”?
Yes. An “overly aggressive” scenario removes not only treatment-related text but also confounder-related text, weakening the proxy relationship between text and the unobserved confounder.
How do I know if I should abstain from using text as a confounder proxy?
If leakage is high and you can’t reliably distill treatment signal, effect estimates can be severely biased; in that case, abstaining from non-distilled text adjustment may be safer.
Does the paper propose automatic distillation methods?
It defines the problem, clarifies assumptions, and uses an oracle distillator in simulation to build intuition. It also points to future work on developing automated approaches.
What’s the simplest practical test for leakage?
Try predicting treatment from text; if treatment is “almost perfectly” predicted and propensities bunch near 0 and 1, you likely have leakage and overlap issues.
What should you do next if you suspect treatment leakage?
Don’t assume your text is a clean proxy. First, diagnose whether text predicts treatment; then distill treatment signal (manually or algorithmically) and re-check. If you can’t reduce leakage without destroying confounder signal, consider alternative identification strategies.
At minimum, bake this into your workflow: Leakage check → Distill → Re-check → Estimate. That simple loop can save you from confidently publishing the wrong causal effect.
–
References
@article{daoud2022conceptualizing,
  title={Conceptualizing Treatment Leakage in Text-based Causal Inference},
  author={Daoud, Adel and Connor T. Jerzak and Richard Johansson},
  journal={Proceedings of the Annual Conference of the North American Chapter of the Association for Computational Linguistics (NAACL)},
  year={2022},
  volume={},
  pages={5638-5645},
  publisher={}
}–
Related Work
@article{pieuchon2024can,
  title={Can Large Language Models (or Humans) Disentangle Text?},
  author={Pieuchon, Nicolas Audinet de and Adel Daoud and Connor T. Jerzak and Moa Johansson and Richard Johansson},
  journal={Proceedings of the Sixth Workshop on Natural Language Processing and Computational Social Science (NLP+ CSS 2024)},
  year={2024},
  pages={57--67},
  publisher={}
}@article{nicolas audinet de pieuchon 2025benchmarking,
title={Benchmarking Debiasing Methods for LLM-based Parameter Estimates},
author={Nicolas Audinet de Pieuchon and Adel Daoud and Connor T. Jerzak and Moa Johansson and Richard Johansson},
journal={Forthcoming in: Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing (EMNLP)},
year={2025},
volume={},
pages={},
publisher={},
doi={}
}@article{libgober2024linking,
title={Linking Datasets on Organizations Using Half-a-Billion Open-Collaborated Records},
author={Libgober, Brian and Connor T. Jerzak},
journal={Political Science Methods and Research},
year={2024},
pages={1-20},
publisher={}
}@article{jerzak2023improved,
title={An Improved Method of Automated Nonparametric Content Analysis for Social Science},
author={Jerzak, Connor T. and Gary King and Anton Strezhnev},
journal={Political Analysis},
year={2023},
volume={31},
number={1},
pages={42-58},
publisher={}
}–