
Authors: Brian Libgober | Connor Jerzak
A guide to linking messy organization names across datasets using a massive LinkedIn-derived name corpus—plus machine learning, network community detection, and an ensemble that beats fuzzy matching on real-world tasks.
TL;DR: This paper shows how to link organization names across datasets when you don’t share IDs or useful covariates—by using a LinkedIn-derived corpus of aliases ↔ organization URLs and training linkage methods on it.
- Why it matters: Fuzzy matching fails on “JPM” vs “Chase Bank”–style cases, causing missed matches or lots of false positives.
- What’s new: A LinkedIn-based training signal enables (1) a Transformer-based similarity model, (2) network/community-detection linkage, and (3) a unified ensemble of both.
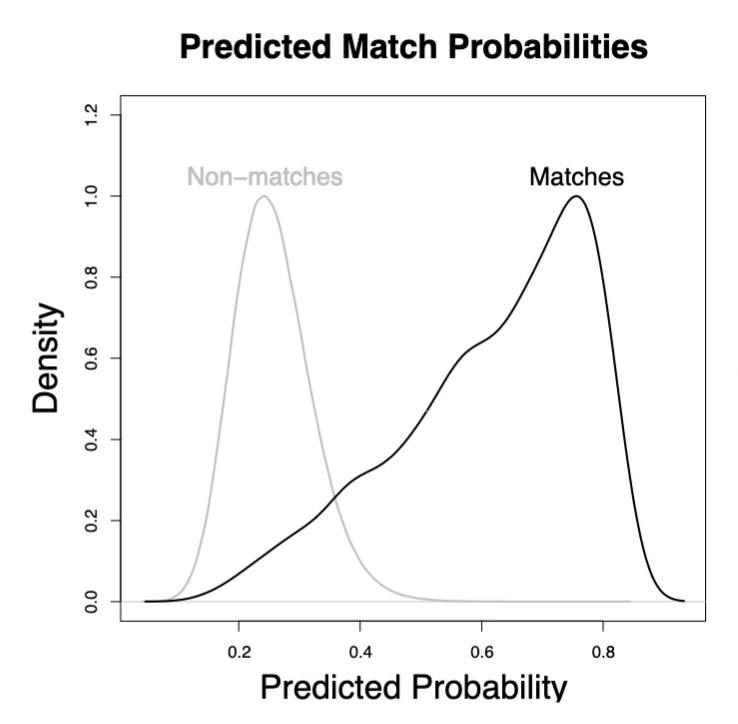
- What you get: Better match separation (higher true positives at comparable error rates), improved downstream analysis quality, and open data + tools (LinkOrgs + Dataverse).
What problem does organizational record linkage solve?
Organizational record linkage is the task of identifying the same organization across datasets that don’t share a universal ID (and often don’t share reliable covariates either), so you can merge data without hand-coding everything.
This is common in political science, public policy, and business research: you might want to connect lobbying disclosures to stock tickers, donations to corporate financials, or nonprofit filings to regulatory actions. The catch is that organizations are named inconsistently across sources—so “The Trump Organization” or “HSBC Holdings PLC” may show up in many variants, abbreviations, or subsidiaries.
The paper Linking Datasets on Organizations Using Half a Billion Open-Collaborated Records tackles this head-on by using a massive LinkedIn-derived “alias directory” to make matches more accurate and less manual.
Why does fuzzy matching often fail for organization names?
Fuzzy matching measures character overlap (or edit distance), so it struggles when two names refer to the same entity but share few characters—or when superficial similarity creates false positives.
The classic failure mode is “JPM” vs “Chase Bank”: humans know they relate, but character-based similarity can be tiny. Another is “Goldman Sachs” vs “Saks Fifth Avenue”: they share phonetic/character patterns, but they’re not the same entity. These are exactly the cases where researchers either (a) miss true matches by tightening thresholds or (b) drown in false positives by loosening them.
Our key move is to bring in behavioral linkage evidence: millions of people have already connected employer name variants to the same LinkedIn organization page, producing a powerful training signal that string metrics alone don’t capture.
What data does the LinkedIn corpus contain?
The dataset is built from publicly visible LinkedIn profiles (circa 2017) where users provide a free-text employer name (“alias”) and often link that alias to a specific LinkedIn company URL.
- Scale: ~350 million public profiles across 200+ countries (near-census of public LinkedIn at the time).
- Alias coverage: 15,270,027 unique employer-name aliases.
- Organization IDs: 5,950,995 unique company URL identifiers.
- Density: Mean ~2.88 aliases per URL; mean ~1.12 URLs per alias.
- Combinatorics: More than 10^{14} alias-pair examples in principle.
Conceptually: each alias is a noisy label (“JP Morgan Chase Bank”, “JPMC”, “Chase”, “Washington Mutual”), and the LinkedIn company URL is a stable identifier that lets you learn which aliases are truly related.
We also make the name-match corpus available via Dataverse (DOI: 10.7910/DVN/EHRQQL) and provide an open-source package called LinkOrgs.
How does the machine-learning approach estimate match probabilities?
The ML approach learns a function that maps an organization name alias to a vector embedding, then trains that model to predict the probability that two aliases refer to the same organization—using LinkedIn alias→URL link patterns as supervision.
At a high level, the method learns an embedding for names from the characters up (characters → words → organization name), producing a 1,024-dimensional representation that can be compared quickly at scale.
The target label isn’t just “ever linked to the same URL.” Instead, it uses a probability based on how often aliases link to each organization URL, inspired by naive Bayes. The paper writes it as:
\Upsilon_{ij}=\Pr(i\text{ and }j\text{ match}\mid A_i=a, A_j=a')=\sum_{u\in\mathcal{U}} \Pr(U_i=u\mid A_i=a)\Pr(U_j=u\mid A_j=a')
Intuition: if both aliases disproportionately point to the same organization URL, their match probability rises; if one alias mostly points elsewhere (or is ambiguous), the probability stays low. This also down-weights rare mistakes (e.g., a one-off mis-linked profile) instead of treating all links equally.
How do network and community-detection methods help?
Network methods treat aliases and organization URLs as a graph, then use community detection to discover “clusters” of aliases that belong together—even when the alias text contains little semantic overlap.
This matters for cases where semantics hit a ceiling: acronyms, legacy brands, subsidiaries, or “you just have to know” relationships. The paper explores Markov clustering and greedy modularity-based clustering, and it highlights a bipartite representation (aliases ↔ URLs) as especially effective.
The result is a practical directory: even if two aliases don’t directly co-occur with the same URL, they can still land in the same community if the network evidence is strong enough (capturing useful, limited transitivity without collapsing everything into giant components).
What is the unified (ensemble) approach—and when is it best?
The unified approach combines ML similarity (good for semantic/character patterns) with network communities (good for “hidden” relationships), so you get the best of both worlds.
It works in two complementary passes:
- Direct matching: Use ML scores to match names across your two datasets (like fuzzy matching—just better trained).
- Indirect matching via directory: Map each dataset’s names into the LinkedIn-derived alias communities and match items that land in the same community.
If your organizations are well-represented in the LinkedIn network, the directory + community step can capture “JPM ↔ Washington Mutual” style links. If your organizations are newer or obscure, the direct ML step can still help because it generalizes from name structure learned on the massive corpus.
How well does it work in real record-linkage tasks?
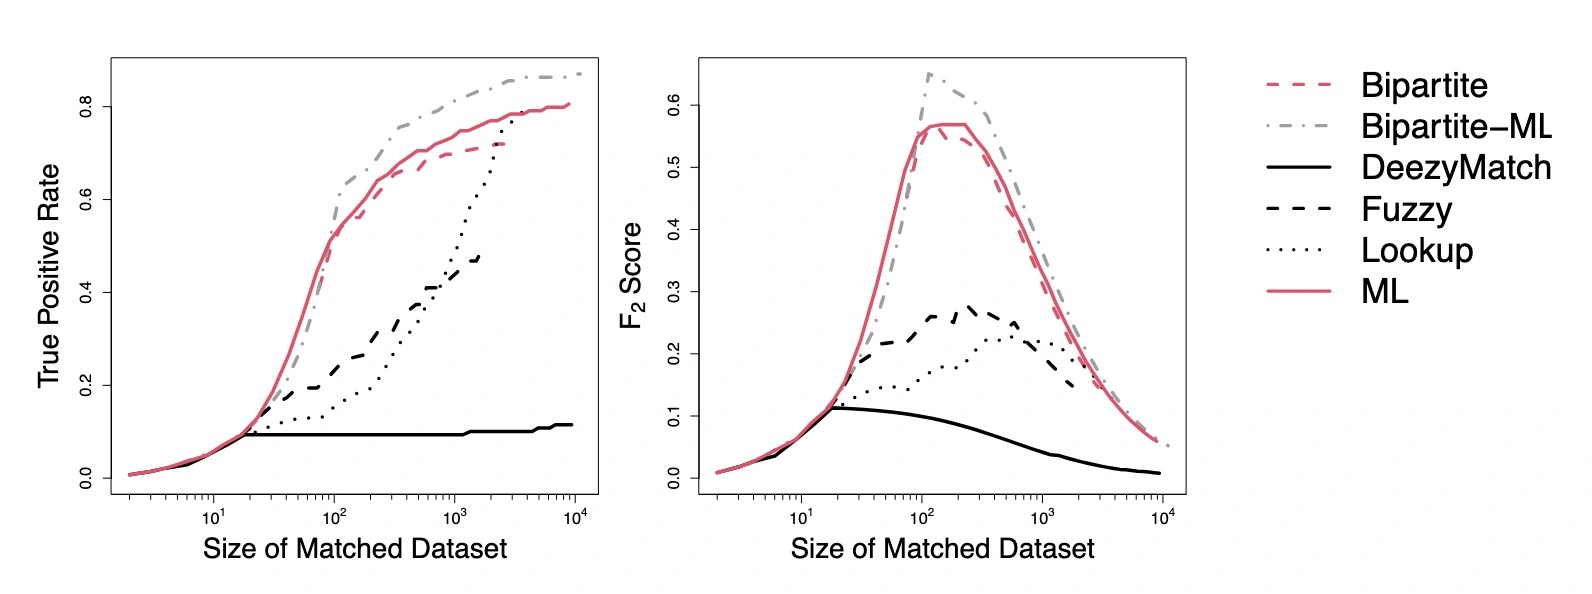
Across multiple evaluation tasks, LinkedIn-assisted methods generally produce higher true-positive rates and better error-adjusted scores than fuzzy matching, and they can materially improve downstream regression results.
Task 1: Lobbying meetings ↔ stock market tickers
In a merge of ~700 organization names to ~7,000 public companies, the LinkedIn-assisted methods achieve substantially better performance across thresholds. A concrete example: fuzzy matching fails to link “HSBC Holdings PLC” to “HSBC,” while the LinkedIn-based directory can recover the match.
Task 2: Fortune 1000 assets ↔ lobbying expenditures
Match quality affects substantive inference: the “true” (human-coded) relationship between firm size and lobbying is large, and fuzzy matching can under-estimate it by about half at its best-performing threshold. LinkedIn-assisted approaches recover coefficients closer to the ground truth.
Task 3: Out-of-sample (Y Combinator startups ↔ PPP loans)
When organizations post-date the 2017 LinkedIn snapshot, network-directory methods offer less advantage—yet the ML approach still helps, because it learned more general name-link patterns than string distance alone.
Key takeaway: If you can only pick one upgrade over fuzzy matching, start with the LinkedIn-calibrated ML approach. If you need the toughest acronym/subsidiary matches and your entities exist in the directory, the ML + network ensemble is the strongest option.
What are the runtime and scaling trade-offs?
The most accurate approaches can be slower, especially when they require comparing candidate names against large directories—so you trade compute for match quality.
On the meetings-data application, the paper reports the following runtimes (minutes):
| Algorithm | Run time (mins) | When to use |
|---|---|---|
| Fuzzy | 0.27 | Quick baseline; expect more misses/false positives |
| ML | 1.63 | Fast + strong general-purpose improvement |
| Bipartite | 13.12 | Directory/community matching when coverage is good |
| Bipartite-ML (ensemble) | 251.38 | Highest-quality merges; pay the compute cost |
The paper also discusses scaling strategies (e.g., parallelization and locality-sensitive hashing) to avoid spending most compute time on obviously unlikely pairs.
How can you apply these ideas in your next dataset merge?
Use the ML model for fast, high-quality candidate generation, then optionally “snap” names into network communities for the hard cases (acronyms, subsidiaries, legacy brands).
A practical workflow
- Normalize lightly: Standardize casing, whitespace, and common punctuation—don’t over-clean away signal.
- Generate candidates: Use the ML similarity/match probability to produce top-k candidates per organization rather than scoring every cross-product pair.
- Decide thresholds with audits: Sample borderline matches for quick human review; adjust the threshold to your tolerance for false positives.
- Use the directory for “semantic dead-ends”: When names share few characters, map them into the LinkedIn-derived communities and match via shared community assignment.
- Keep uncertainty: Save match probabilities and/or multiple candidates so you can run sensitivity checks later.
Which method should you choose?
| Goal | Best choice | Why |
|---|---|---|
| Fast improvement over fuzzy matching | LinkedIn-calibrated ML | Generalizes well; low runtime; better separation than string distance |
| Catch acronyms/subsidiaries/brand families | Network/community detection | Uses real-world alias↔URL linkage structure |
| Highest-quality merges (when coverage exists) | Unified ensemble (ML + network) | Combines semantic and graph-theoretic evidence |
What are the limitations—and how should you handle them?
The biggest limitation is coverage drift: a 2017 LinkedIn snapshot won’t fully represent organizations that didn’t exist (or weren’t well-documented) at that time.
- Out-of-sample organizations: Expect less benefit from directory/community methods; lean more on the ML model’s generalization.
- Compute constraints: For very large merges, use candidate generation (top-k), blocking, or LSH to avoid scoring all pairs.
- Legal/ethical constraints: If you plan to scrape or acquire similar data today, ensure compliance with applicable laws, platform terms, and institutional review requirements; the paper discusses the legal context of public-profile scraping.
FAQ
What is “record linkage” vs “entity resolution”?
Answer: They’re closely related: both aim to determine whether two records from different sources refer to the same real-world entity (here, an organization).
Is this only for political science datasets?
Answer: No. Any domain with messy organization names—finance, compliance, procurement, nonprofits, academic institutions—can benefit from the same ML + network approach.
Do I need the full LinkedIn corpus to benefit?
Answer: Not necessarily. If you can access our released directory/model artifacts, you can apply the approach without re-building the corpus yourself. The ML approach is especially reusable.
How should I choose a match threshold?
Answer: Choose it based on your tolerance for false positives: if you can quickly review proposed matches, set a looser threshold to maximize recall; if false positives are very costly, tighten the threshold and/or require multiple signals (ML + network agreement).
What evaluation metric should I use?
Answer: If missing true matches is worse than reviewing some false positives, use an F-score that weights false negatives more (the paper uses F_2). Otherwise, tune to your project’s cost function.
Online Interface to LinkOrgs
–
LinkOrgs Training Data: >1T Training Pairs from the LinkedIn Network
–
Figures from the Paper
–
References
@article{libgober2024linking,
  title={Linking Datasets on Organizations Using Half-a-Billion Open-Collaborated Records},
  author={Libgober, Brian and Connor T. Jerzak},
  journal={Political Science Research and Methods},
  year={2024},
  pages={1-20},
  publisher={}
}–
Related Work
@article{pieuchon2024can,
  title={Can Large Language Models (or Humans) Disentangle Text?},
  author={Pieuchon, Nicolas Audinet de and Adel Daoud and Connor T. Jerzak and Moa Johansson and Richard Johansson},
  journal={Proceedings of the Sixth Workshop on Natural Language Processing and Computational Social Science (NLP+ CSS 2024)},
  year={2024},
  pages={57--67},
  publisher={}
}@article{jerzak2023improved,
title={An Improved Method of Automated Nonparametric Content Analysis for Social Science},
author={Jerzak, Connor T. and Gary King and Anton Strezhnev},
journal={Political Analysis},
year={2023},
volume={31},
number={1},
pages={42-58},
publisher={}
}@article{daoud2022conceptualizing,
title={Conceptualizing Treatment Leakage in Text-based Causal Inference},
author={Daoud, Adel and Connor T. Jerzak and Richard Johansson},
journal={Proceedings of the Annual Conference of the North American Chapter of the Association for Computational Linguistics (NAACL)},
year={2022},
volume={},
pages={5638--5645},
publisher={Association for Computational Linguistics},
doi={10.18653/v1/2022.naacl-main.413}
}–